De Workstation-blog
AI
Berichten met de tag AI.
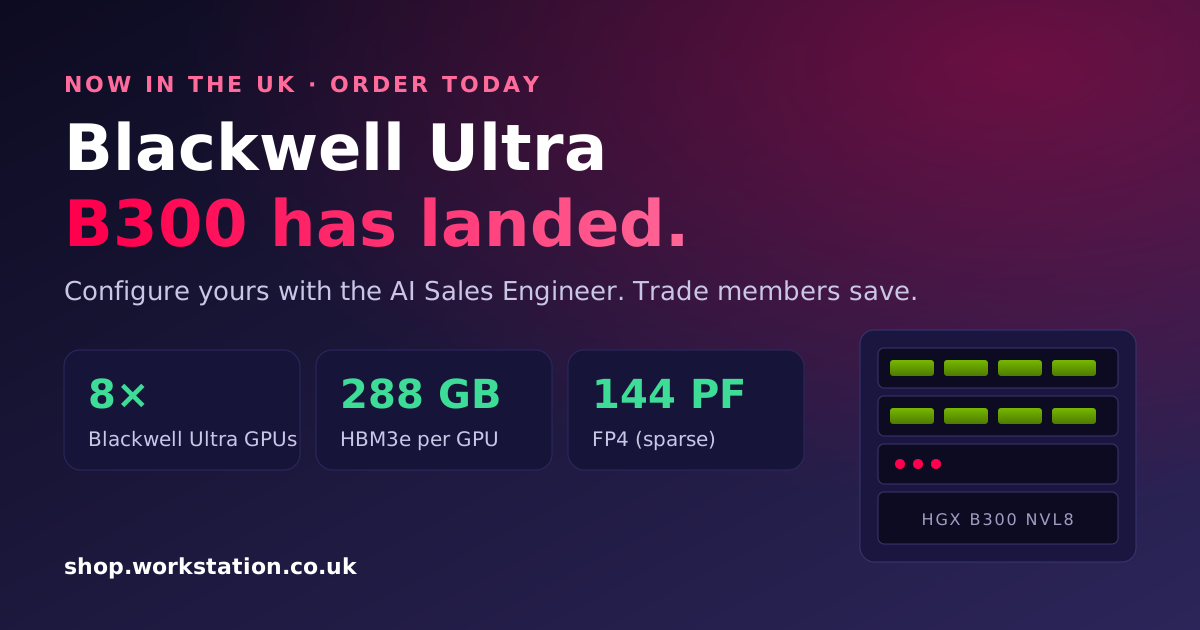
NVIDIA Blackwell Ultra B300 is in het VK geland: configureer de uwe vandaag
NVIDIA Blackwell Ultra B300-systemen zijn aangekomen bij onze Britse distributiepartners. Configureer en prijs uw B300-build met acht GPU's in enkele minuten met onze AI Sales Engineer, bespaar met Workstation Trade en bestel vandaag om als eerste aan de beurt te zijn wanneer de Britse voorraad binnenkomt.
 Balinder WaliaLezen
Private AI voor advocatenkantoren: een offline-first workstation kiezen die uw cliënten kunnen vertrouwen
Hoe een advocatenkantoor een private-AI-workstation kiest die zonder internetverbinding draait: wie hem gebruikt, welk model, hoeveel GPU-geheugen, hoe geïsoleerd hij moet zijn en wie hem installeert. Met echte prijzen uit een echte offerte, waar die te zwaar was gespecificeerd, en de Starter-, Workforce- en Enterprise-builds die wij daadwerkelijk zouden leveren.
Balinder WaliaLezen 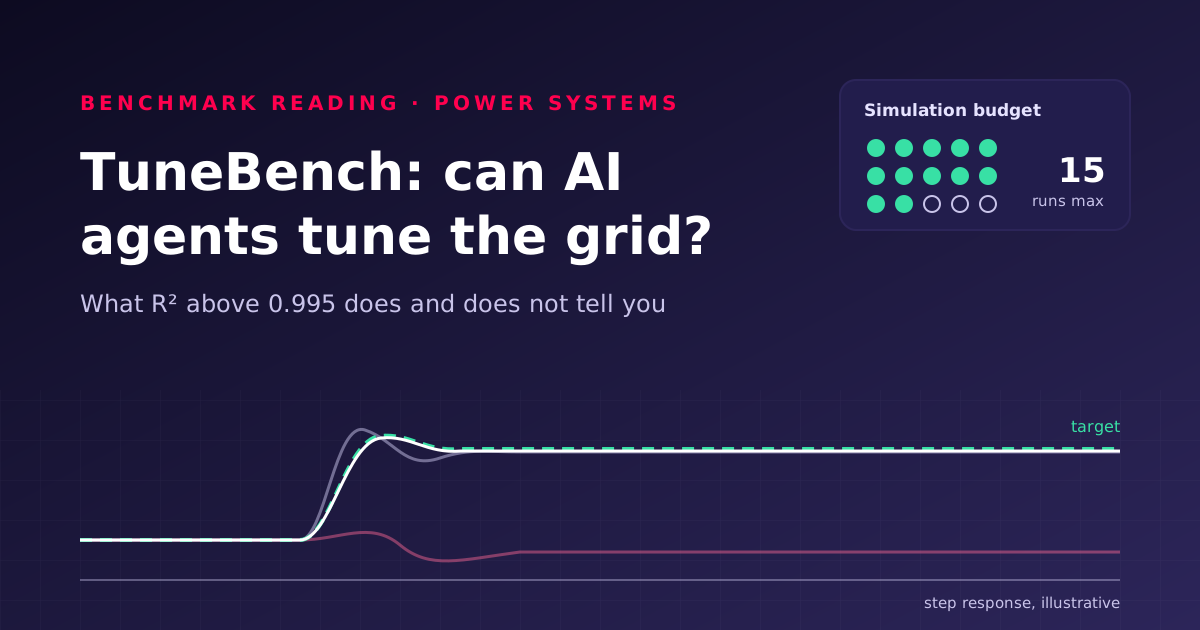
TuneBench: How Well Can AI Agents Calibrate Power System Models?
TuneBench tests LLM agents on calibrating generator and battery models within 15 simulations. Only Opus 5.5 and GPT-6 hit median R² above 0.995 in every test. What that figure means, its limits, and how to build the same kind of benchmark.
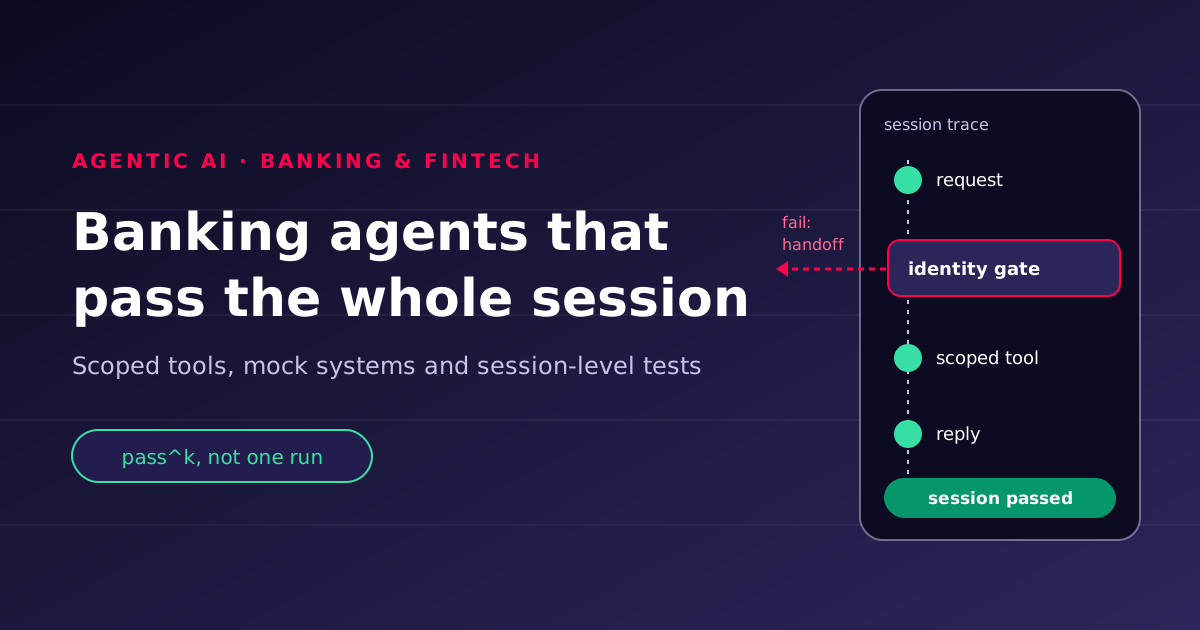
Agentic AI in banking: efficiency you can defend to a risk committee
Banking AI agents rarely fail on one bad reply; they fail across a session. How to scope tools, test whole conversations against mock systems and measure reliability with pass^k, so the time saved survives audit and production.
Wikipedia banned AI-written articles: what teams that reuse it should change
English Wikipedia now prohibits LLM-written article text, yet volunteers still flag a steady share of new drafts as AI-generated. If your search, chatbot or knowledge base reuses Wikipedia, here is how to pin revisions, watch edits, review changes and attribute correctly.
Trading costs with agents: what an AI agent really costs to run
AI agents move cost rather than remove it. Learn why the token bill grows with the square of loop steps, how caching and compaction bend the curve, and a playbook for pricing, budgeting and capping an agent before it reaches production.
The energy cost of LLM code optimisation, and when it pays back
A 2026 study found LLM-optimised code used more energy per run than the human reference in 42 of 44 configurations. Learn the break-even rule, how to measure joules per run on Linux, and a workflow for keeping only the rewrites that pay back.
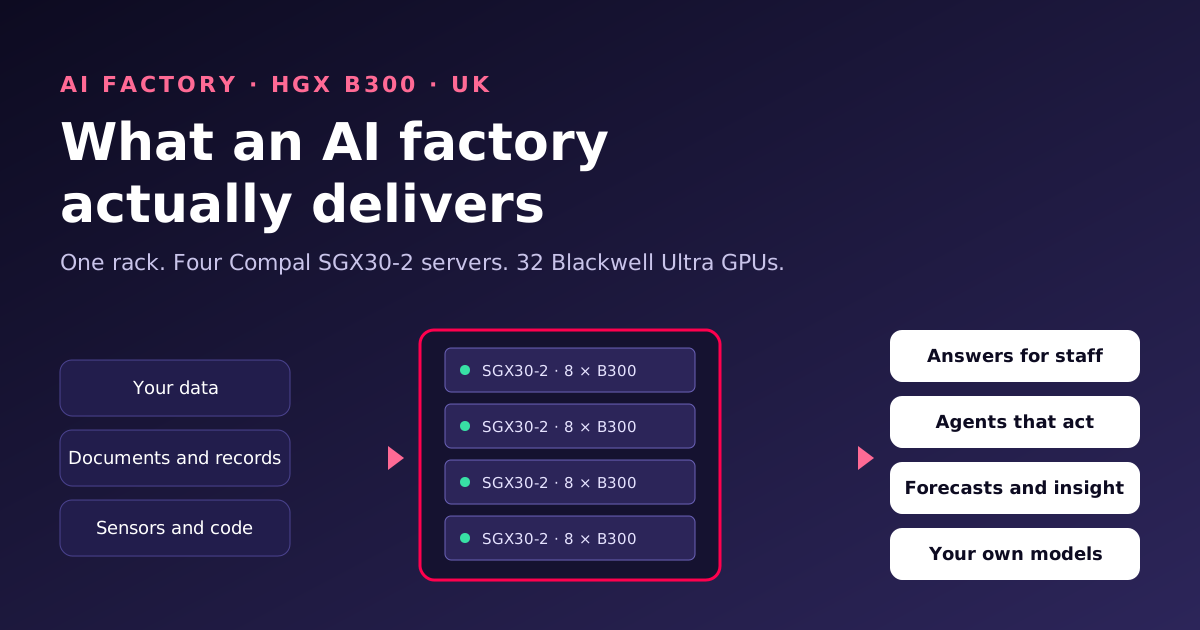
Wat een AI-fabriek werkelijk oplevert: één rack, 32 Blackwell Ultra-GPU's en het werk dat het voor u doet
Een AI-fabriek zet uw eigen data om in antwoorden, agents, prognoses en getrainde modellen op hardware die u zelf beheert. Hier leest u wat erin gaat, wat eruit komt, hoe het werk dagelijks verloopt en wat een rack met vier Compal SGX30-2-servers met 32 NVIDIA Blackwell Ultra-GPU's nodig heeft om te draaien.
Balinder WaliaLezen 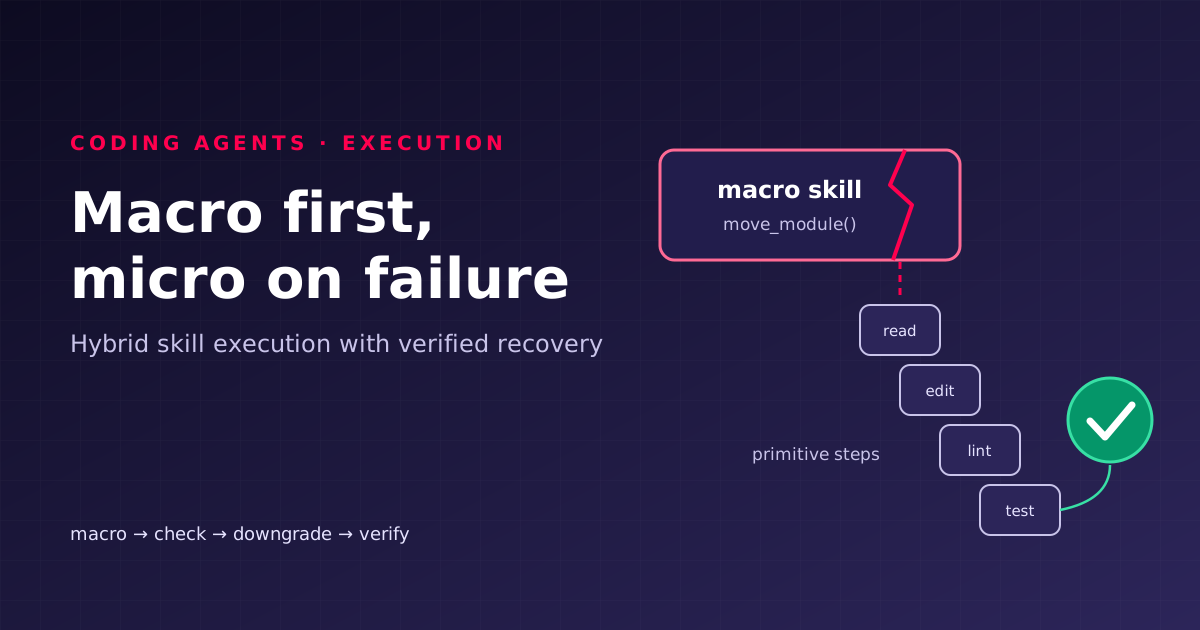
Hybrid Execution for Coding Agents: Macro Skills, Micro Recovery
Bundled macro skills make coding agents cheap but brittle; primitive tool calls make them robust but costly. Here is how to run macros first, verify every result, and fall back to small steps only when the workspace shows it is needed.
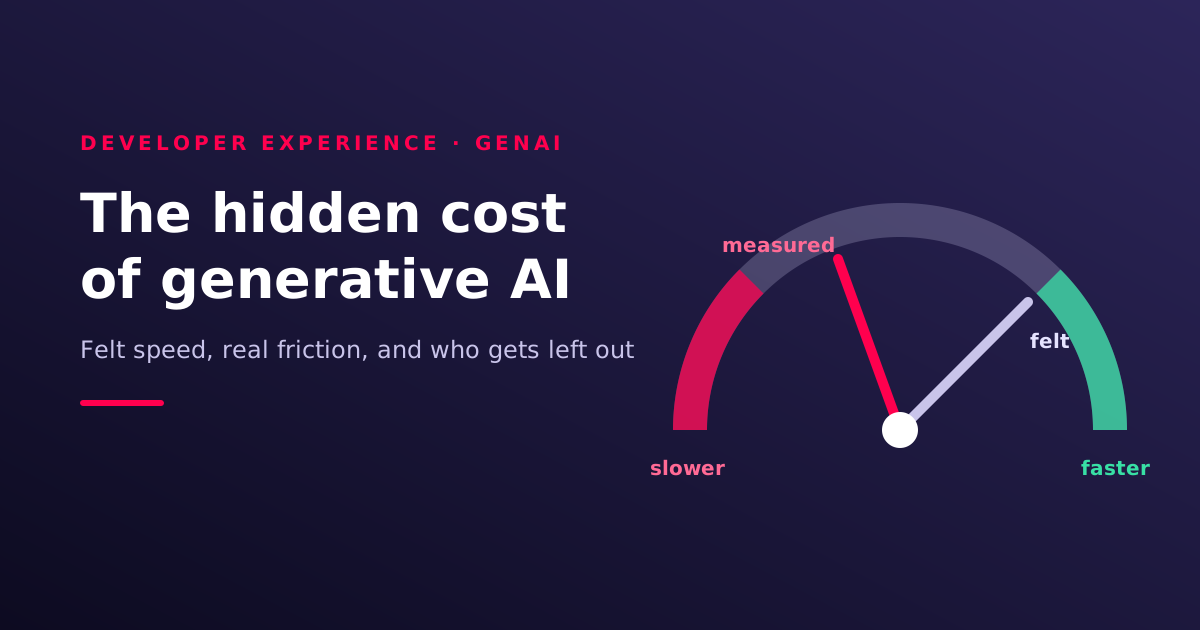
Generative AI's Hidden Impact on Developers: What Surveys Miss
Developers say AI makes them faster, but the evidence shows hidden costs: almost-right answers, a gap between felt and measured speed, tool admin work and accessibility barriers. Here is what the research says and how to measure it in your team.