Monitoring AI-Powered Systems

The Importance of Observability in AI-Powered Systems
AI-powered systems are services whose core outputs are generated by models, agents or retrieval-augmented components, rather than deterministic code paths. Unlike traditional services, where latency, error rate and throughput describe behaviour, AI systems add non-deterministic outputs, model drift, prompt sensitivity, retrieval quality and cost per decision to the picture.
For teams in Banking, Education, HealthTech, FinTech and Tax Returns, the consequences of a blind spot are sector specific. In banking and fintech, a degraded agent can misprice risk or misinterpret a compliance question. In healthtech, an unreliable recommendation can affect triage or documentation. In education, an inconsistent tutor can erode trust with students and teachers. In tax returns, an incorrect extraction can create filing errors with regulatory exposure.
Observability matters because it connects model behavior to business outcomes. Without it, teams optimize prompts in isolation and discover problems only after users report them.
Designing and Implementing Observability Pipelines
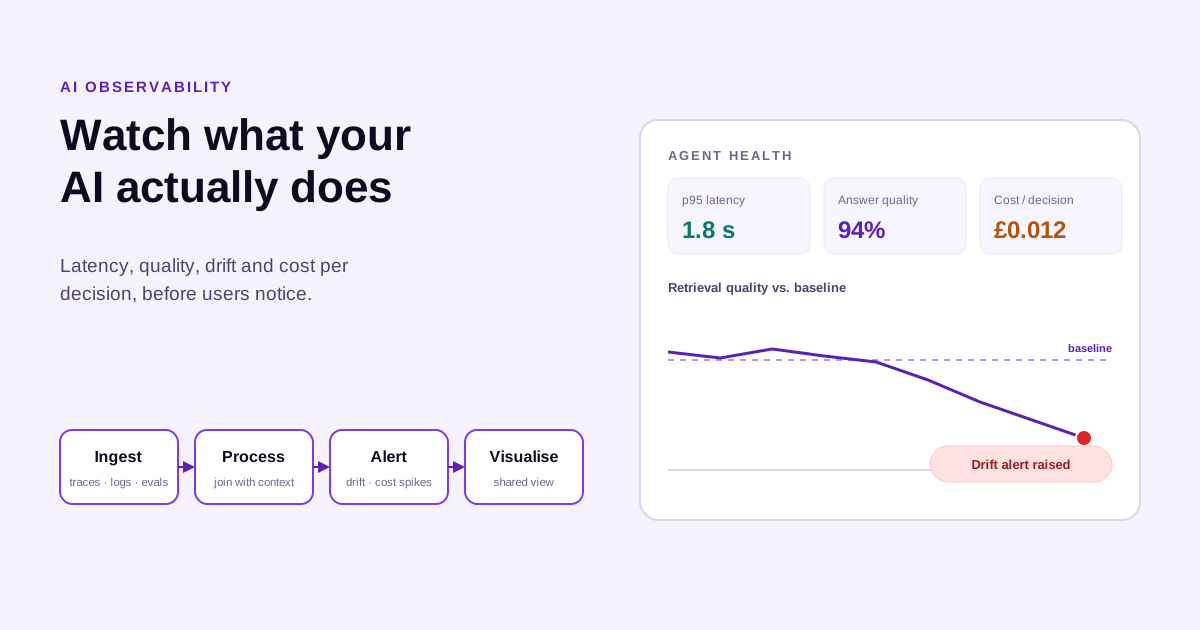
A practical observability pipeline for AI systems can be described as four concerns: data ingestion, data processing, alerting and notification, visualization and analysis.
Data ingestion is where traces, logs, metrics and agent evaluation scores enter the system. Data processing normalizes those signals and joins them with operational context. Alerting and notification surfaces anomalies before they compound. Visualization and analysis gives product and engineering a shared view of behavior over time.
The following sequence shows how an agent request typically flows through observability instrumentation.
Keeping the pipeline simple at first is a best practice. Start with a single source of truth for traces and attach evaluation scores to each invocation. Add cost and latency signals early, because they are the first indicators that a change is not production-ready.
Successful Observability Strategies in Banking, Education, HealthTech, FinTech, and Tax Returns
The subject means something different in each sector, so examples should be chosen accordingly rather than padded with generic vocabulary.
In Banking and FinTech, observability is tied to risk and auditability. Online experiments combine agent evaluation scores with operational measurements such as latency, token consumption, execution cost, and errors [1]. That combination helps teams establish whether changes to models, prompts, retrieval strategies, or tools actually improve an agent. Datadog's approach brings controlled experimentation, production telemetry, and execution traces together, giving teams evidence of both the outcome and the behaviour behind it [1].
In Tax Returns, accuracy and reproducibility dominate. Observability pipelines log the exact inputs, the extracted fields and the confidence scores. Because tax rules change annually, versioning of both model and rule set is tracked alongside each filing.
In HealthTech, privacy constraints shape the pipeline. Teams often use anonymized embeddings and aggregate metrics rather than raw text in dashboards. Observability focuses on consistency of clinical terminology and on guardrail triggers rather than on free-form output.
In Education, the focus is on pedagogical effectiveness and fairness across cohorts. Observability tracks whether explanations are consistent, whether hints escalate appropriately, and whether latency degrades the learning flow.
Sector-aware success criteria are the business-level outcomes that define what “good” means for a given sector and agent. They are used to inform observability practices by selecting which metrics to collect, which guardrails to enforce and what thresholds trigger alerts. For example, banking success criteria emphasize risk and auditability, while education emphasizes pedagogical effectiveness and fairness.
A common pattern across sectors is the use of online experiments to reduce noise. Online experiments can reduce the influence of differences in user requests by randomly distributing production traffic between control and modified variants [1]. This is valuable in banking and tax where user inputs are highly variable and offline benchmarks do not generalize.
Tools and Technologies for Observability
Tool choice is a trade-off between control, cost and time to value.
| Category | Example | When it fits |
|---|---|---|
| Agent observability platform | Datadog | Teams that want controlled experimentation with production telemetry and execution traces together |
| ML governance | Arthur Engine | Teams that need a complete service for developing, monitoring, and governing AI/ML workloads using popular open-source technologies and frameworks [2] |
| Evaluation and tracing | Laminar | Teams that need frontend AI features and server-side AI workers and want Postgres/ClickHouse backed storage |
| Legacy integration | legacy-use | Organizations that need to expose legacy applications with REST-APIs, enabling you to build reliable solutions and automate workflows where it was not possible before [3] |
The Arthur Engine supports a wide range of evaluation metrics, including drift, accuracy, precision, recall, F1, and AUC [2]. It also allows for extensibility to fit into an application's architecture, with native support for custom metrics and an extensible API [2]. The enterprise version of the Arthur Platform provides better performance, additional features, and capabilities, including custom enterprise-ready guardrails + metrics [2].
For teams self-hosting observability, implementation details matter. The frontend creates a read-only role in Postgres for ClickHouse to read from [4]. Self-hosted deployments send Laminar a usage report every 6 hours: the Laminar version and environment, row counts per table, which features are enabled, the enterprise license status and trial dates, and the email domains of the instance's users [4]. The frontend can be configured to use a custom Postgres schema [4]. Frontend AI features and server-side AI workers require an LLM provider [4].
Legacy systems remain a reality in banking and tax. Our vision is to change that. We expose legacy software through REST-API interfaces, making it accessible to agents and modern automation tools [3]. legacy-use simplifies the work of building and maintaining integrations across platforms [3]. The vendor notes 20 min to qualify one workflow for AI-RPA, UiPath, or API automation [3].
Best Practices for Implementing Observability in AI-Powered Systems
Start with a contract for what you will measure. For each agent, define outcome metrics, guardrail metrics and cost metrics. Keep the set small enough to be actionable.
Instrument at the agent boundary, not just the model. Traces should include prompt, retrieval context, tool calls and final output. This makes root cause analysis possible when behavior degrades.
Treat prompts and retrieval indexes as versioned artifacts. Observability is useless if you cannot map a production incident to a specific prompt version and data snapshot.
Controlled rollout is the practice of releasing a model, prompt or tool change to a subset of production traffic while keeping the remainder on a control variant. It is used to inform observability practices by enabling direct comparison of business and operational metrics under real user load. Randomly distribute production traffic between control and modified variants to reduce the influence of differences in user requests [1]. Combine evaluation scores with operational measurements such as latency, token consumption, execution cost, and errors [1] so that improvements are not just better on a benchmark.
Design for privacy and compliance by default. In HealthTech and Banking, avoid storing raw PII in observability stores. Aggregate and tokenize where possible.
Plan for legacy integration early. In banking and tax, many critical workflows live in legacy applications. Exposing legacy applications with REST-APIs, enabling you to build reliable solutions and automate workflows where it was not possible before [3] reduces the temptation to bypass observability.
Review and prune. Observability pipelines accrue cost. Regularly audit dashboards, alerts and stored traces. Keep what drives decisions, archive the rest. A concrete example is removing high-cardinality trace fields that are never queried and archiving raw agent transcripts older than 30 days while retaining aggregated metrics.
Observability for AI is an ongoing practice, not a dashboard. Teams that pair disciplined instrumentation with sector-aware success criteria can ship model changes with confidence and explain their behavior when it matters.
References
- Datadog Brings Production Experimentation to AI Agent Observability — infoq.com
- arthur-ai/arthur-engine — github.com (18 November 2026)
- legacy-use — legacy-use.com (14 July 2025)
- lmnr-ai/lmnr — github.com (17 November 2026)