LLM Inference Boosts 4-5x with NVIDIA Grace

Desktop-scale clusters are moving from prototype curiosity to operational reality for manufacturing, supermarkets, banking, education, healthtech, fintech and tax returns.
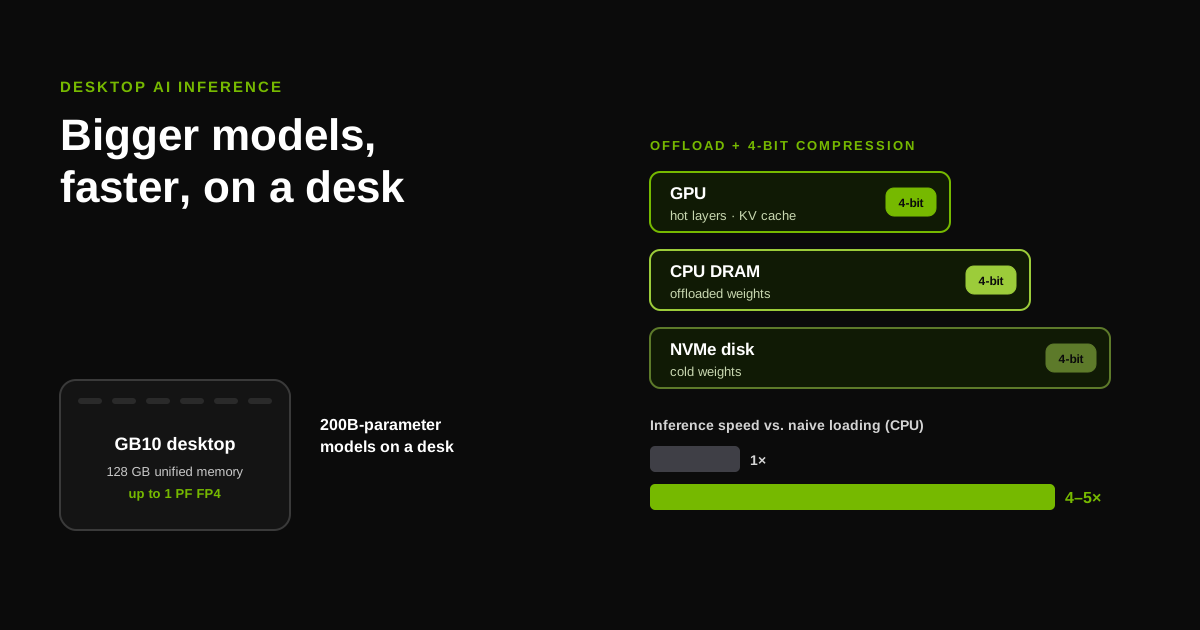
The NVIDIA Grace Blackwell GB10 Superchip is positioned as the desktop anchor for this shift. The GB10 Superchip delivers up to 1 petaflop of AI performance at FP4 precision [1]. Each Project DIGITS features 128GB of unified, coherent memory and up to 4TB of NVMe storage [1]. With the supercomputer, developers can run up to 200-billion-parameter large language models to supercharge AI innovation [1].
Challenges and Opportunities
For regulated and operationally constrained industries, the challenge is not just model size. It is memory, energy and consistency at the edge of the plant, branch or campus.
Large language models exceed single-GPU memory, so inference requires either model parallelism, offloading, or compression. FlexGen can be flexibly configured under various hardware resource constraints by aggregating memory and computation from the GPU, CPU, and disk [2]. FlexGen further compresses the weights and the attention cache to 4 bits with negligible accuracy loss [2].
Methods collectively enable running models up to twice the size of the available DRAM, with a 4-5x and 20-25x increase in inference speed compared to naive loading approaches in CPU and GPU, respectively [3]. For a supermarket chain running private product description generation or a bank drafting compliant explanations, that speedup turns a batch overnight job into an interactive tool.
Energy and latency trade-offs remain. One Spark uses less GPU energy per output token at matched concurrency [4]. That matters in manufacturing where floor systems run 24/7 and in healthtech where power budgets are tied to clinical facilities.
Benchmarking Process and Results
Benchmarking desktop inference must mirror production request patterns, not just peak tokens per second.
A typical evaluation flow can be modeled as:
TP=2 delivers a median 1.59x peak-throughput gain over one Spark, versus 1.39x for PP=2 [4]. TP=2 also reduces unloaded inter-token latency to 0.52x to 0.73x of one Spark, whereas PP=2 provides little reduction [4]. TP=2 also achieves the highest goodput under a strict 100 ms inter-token latency objective wherever both strategies are supported and the objective is met [4].
These results are relevant for sectors with strict service-level expectations. A fintech fraud review assistant or an education tutoring bot needs consistent inter-token latency, not just average throughput. In contrast, a nightly tax document summarization batch may prioritize throughput and energy.
| Strategy | Peak Throughput Gain vs 1 Spark | Unloaded Inter-Token Latency | Goodput at 100 ms latency objective | Energy per token at matched concurrency |
|---|---|---|---|---|
| TP=2 | median 1.59x [4] | 0.52x to 0.73x [4] | highest where supported [4] | higher than one Spark [4] |
| PP=2 | median 1.39x [4] | little reduction [4] | lower than TP=2 [4] | — |
| One Spark | baseline | baseline | baseline | less GPU energy per token [4] |
FlexGen’s own benchmarking demonstrates practical limits. When running OPT-175B on a single 16GB GPU, FlexGen achieves significantly higher throughput compared to state-of-the-art offloading systems, reaching a generation throughput of 1 token/s for the first time with an effective batch size of 144 [2]. On the HELM benchmark, FlexGen can benchmark a 30B model with a 16GB GPU on 7 representative sub-scenarios in 21 hours [2].
FlexGen: Flexible Configuration Framework
FlexGen is presented as a high-throughput generation engine for running LLMs with limited GPU memory [2]. The key claim for desktop operators is flexibility: it can be flexibly configured under various hardware resource constraints by aggregating memory and computation from the GPU, CPU, and disk [2].
Compression is central to that flexibility. FlexGen compresses the weights and the attention cache to 4 bits with negligible accuracy loss [2]. For a healthtech deployment handling de-identified notes, or a bank running on-prem policy QA, the ability to fit larger models into 128GB unified memory without cloud egress is operationally decisive.
Throughput gains are measurable. FlexGen achieves a generation throughput of 1 token/s for the first time with an effective batch size of 144 when running OPT-175B on a single 16GB GPU [2]. Benchmarking speed also improves: FlexGen can benchmark a 30B model with a 16GB GPU on 7 representative sub-scenarios in 21 hours on the HELM benchmark [2].
TensorRT-LLM: Optimized Large Language Model Inference
TensorRT-LLM is the NVIDIA software stack for production inference. TensorRT-LLM includes fully optimized, ready-to-run versions of many LLMs widely used in production today [5].
In-flight batching enables improved GPU usage and minimally doubles the throughput on a benchmark of real-world LLM requests on NVIDIA H100 Tensor Core GPUs [5]. FP8 quantization retains higher accuracy compared to other data formats like INT8 or INT4 while achieving the fastest performance and offering the simplest implementation [5].
A minimal Python invocation pattern looks like:
import tensorrt_llm
llm = tensorrt_llm.LLM(model_name="meta-llama/Llama-3-8B")
output = llm.generate("Summarize this production log:", max_tokens=256)
The ready-to-run models and Python API lower the barrier for teams in manufacturing and education who lack dedicated ML infrastructure engineers.
Implications for Developers
For developers in manufacturing, supermarkets, banking, education, healthtech, fintech and tax returns, desktop-scale clusters change the deployment calculus.
First, privacy and compliance become easier. With 128GB unified coherent memory and up to 4TB NVMe per Project DIGITS unit [1], sensitive data can stay on-prem. That is critical for healthtech clinical documentation and tax return processing where data residency is non-negotiable.
Second, iteration speed improves. The 4-5x inference speed increase compared to naive loading approaches in CPU [3] shortens experiment cycles for prompt tuning and evaluation. A supermarket merchandising team can test dozens of product copy variants in an afternoon instead of overnight.
Third, trade-offs must be explicit. TP=2 improves latency and goodput under a 100 ms inter-token objective [4] but One Spark uses less GPU energy per output token at matched concurrency [4]. For a 24/7 manufacturing copilot, energy may dominate; for an interactive banking chatbot, latency dominates.
Developers should benchmark with their own request mix, measure goodput under latency SLOs, and evaluate energy per token. Desktop Grace Blackwell hardware gives them a realistic path to run up to 200-billion-parameter models locally [1] without rebuilding data pipelines for the cloud.
The net effect is practical: LLMs become a deployable component rather than a research experiment, with measurable throughput, latency and cost metrics that map directly to operational outcomes in regulated industries.
References
- NVIDIA Puts Grace Blackwell on Every Desk and at Every AI Developer’s Fingertips — nvidianews.nvidia.com (7 January 2025)
- [2303.06865] FlexGen: High-Throughput Generative Inference of Large Language Models with a Single GPU — arxiv.org (14 March 2023)
- LLM in a flash: Efficient Large Language Model Inference with Limited Memory — arxiv.org (24 January 2024)
- Benchmarking LLM Inference on Desktop-Scale NVIDIA Grace Blackwell Clusters — arxiv.org
- NVIDIA TensorRT-LLM Supercharges Large Language Model Inference on NVIDIA H100 GPUs — developer.nvidia.com (8 September 2023)