Accelerating AI with NVIDIA's CUDA and Inference

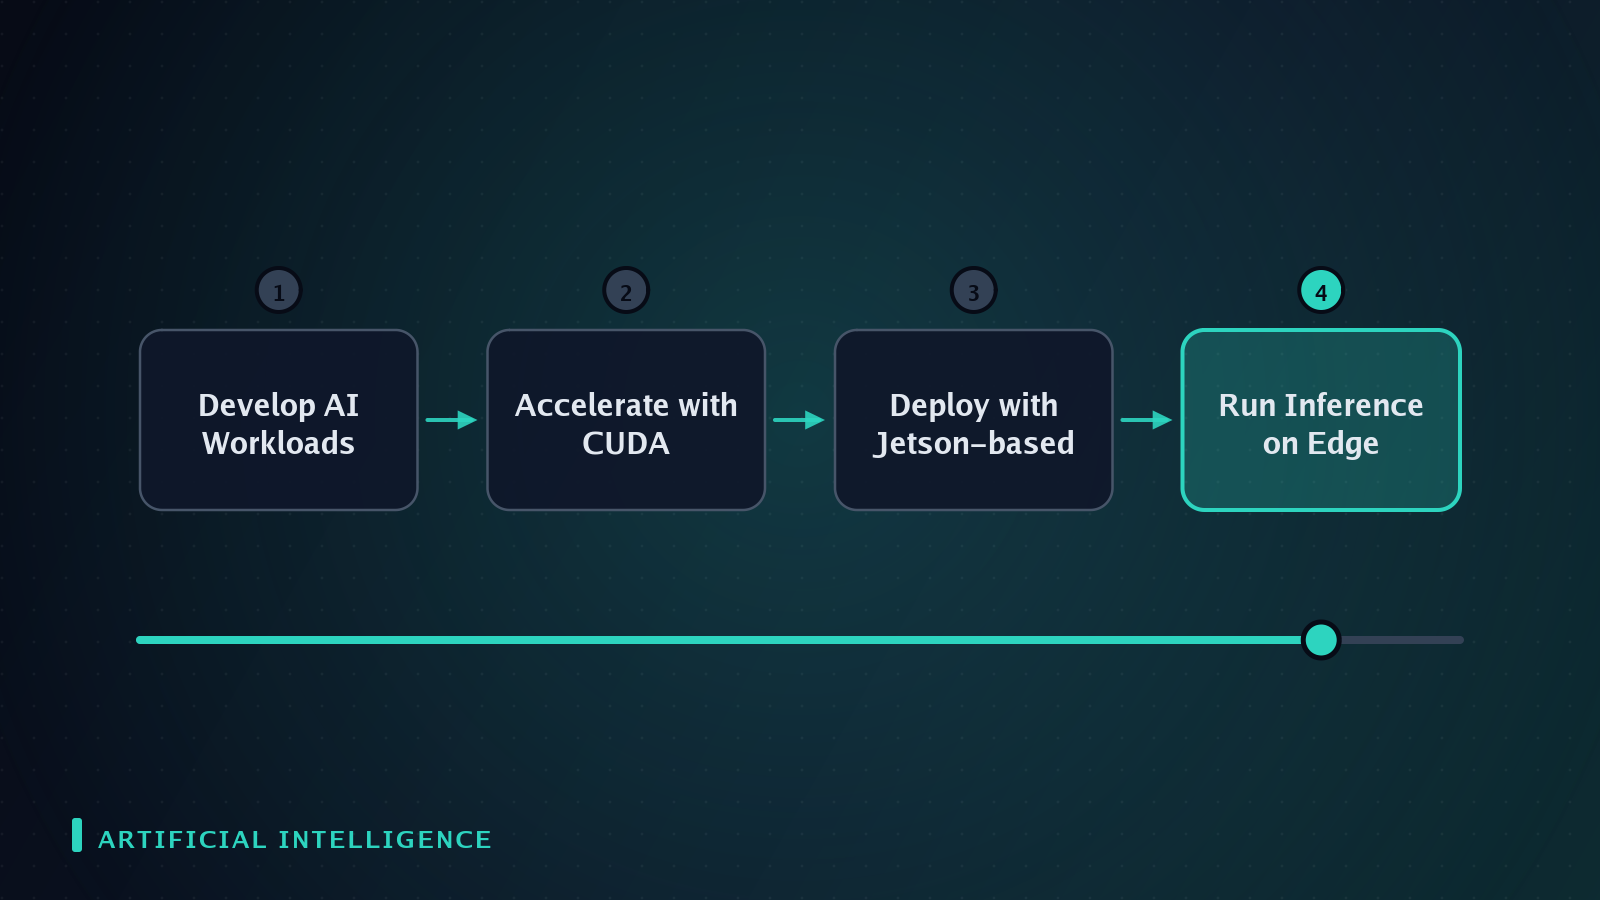
The rapid evolution of artificial intelligence has created a distinct challenge for developers: bridging the gap between high-level model training and efficient, secure deployment in real-world environments. This dichotomy is particularly evident when comparing the raw computational power required for training against the efficiency demands of inference on edge devices. NVIDIA's ecosystem, specifically through CUDA, addresses the performance ceiling, while frameworks like Roboflow's Inference project offer a streamlined path for deployment. Together, these tools represent a significant shift in how AI applications are built, scaled, and secured.
CUDA: Accelerating AI Workloads
At the heart of high-performance AI development lies the need to utilize parallel processing capabilities. Graphics Processing Units (GPUs) have long been the engine of choice for deep learning, but unlocking their potential requires specialized programming models. NVIDIA’s Compute Unified Device Architecture (CUDA) provides the foundational software layer that allows developers to write code optimized for these hardware accelerators.
For developers working with modern AI stacks, CUDA is not merely an optional add-on but a critical component for optimizing performance. When deploying AI workloads, the system can leverage NVIDIA CUDA for GPU acceleration to handle intensive matrix multiplications and tensor operations [1]. This capability is essential because AI models rely on massive amounts of parallel computation that central processing units (CPUs) often struggle to match in throughput for these specific tensor operations.
The integration of CUDA into the AI development lifecycle ensures that when a model is ready for production, it can run on hardware that is specifically designed for such tasks. The inference server, for instance, attempts to automatically choose the optimal container to optimize performance on the machine, including utilizing GPU acceleration via NVIDIA CUDA when it is available [1]. This automation reduces the cognitive load on developers, allowing them to focus on the logic of the application rather than the low-level driver management.
Figure 1: The flow of processing from the GPU hardware through the CUDA kernel to the final accelerated workload.
The relationship between the hardware and the software is direct. The GPU provides the parallel cores, the CUDA kernel translates the computational logic into instructions those cores can execute, and the result is an accelerated AI workload. This triad is the backbone of modern AI performance.
Jetson-based Flowbox: Secure Computer Vision
While cloud-based GPUs handle the heavy lifting of training and large-scale inference, many real-world applications require on-premises or edge computing. This is particularly true in industries like manufacturing and logistics, where data privacy, low latency, and offline capability are paramount. This is where the NVIDIA Jetson-based Flowbox emerges as a specialized solution.
The NVIDIA Jetson-based Flowbox is a ruggedized computer vision (CV) center that is pre-configured with Inference and optimized for running in secure networks [1]. It is not a generic computer; it is a purpose-built device designed to handle the physical demands of industrial environments while maintaining a secure boundary for data processing.
For manufacturers and logistics operators, the ability to process video data locally is often a requirement, not a preference. Sending sensitive production line data to a public cloud can be prohibitively slow or a security risk. The Flowbox addresses this by acting as a self-contained unit. It runs the Inference framework, ensuring that the computer vision models are ready to deploy without the friction of a complex setup.
The architecture of such a system is distinct from standard server setups. Instead of a client-server model where data travels over a network, the Flowbox encapsulates the data ingestion, processing, and output within a single, ruggedized chassis. This is critical for secure networks where external connectivity might be restricted or monitored.
Figure 2: Data flow within the Jetson-based Flowbox, illustrating local processing and secure output within a restricted network.
The Flowbox is particularly relevant for use cases where the "last mile" of AI deployment is the hardest part. It bridges the gap between the abstract model weights and the physical world, providing a tangible, secure hardware solution for computer vision tasks.
Inference: Open-Source AI Framework
The software layer that ties these hardware components together is critical. Roboflow’s Inference project provides an open-source framework that simplifies the deployment of AI models across various hardware platforms. A key aspect of this framework is its licensing: the core of Inference is licensed under Apache 2.0 [1]. This open-source license is significant for enterprise adoption, as it allows for commercial use, modification, and distribution without the legal complexities often associated with proprietary software.
Inference is designed to be hardware-agnostic. It can run on a wide range of hardware, from beefy cloud servers to tiny edge devices [1]. This flexibility is a major advantage in the current AI landscape, where there is no "one-size-fits-all" hardware solution. A developer might need to run the same model in a cloud-based Kubernetes cluster and also on a Jetson module inside a robot. Inference abstracts these differences, providing a consistent interface for model loading and prediction.
The framework handles the complexities of model serving, such as batching requests, managing memory, and optimizing for the specific hardware it is running on. This is done through the use of containers, which ensure that the dependencies are packaged correctly for the target environment.
Figure 3: High-level architectural components of the Inference framework, showing how it manages models, hardware, and serving.
The value of Inference lies in its reduction of friction. By providing a standardized way to deploy models, it allows developers to focus on the application logic. The framework ensures that the model is loaded correctly, that the data is preprocessed, and that the inference is executed efficiently, regardless of whether the underlying hardware is a NVIDIA GPU in the cloud or a Jetson module at the edge.
Real-World Applications and Use Cases
The combination of NVIDIA’s hardware acceleration, secure edge devices, and open-source frameworks enables a variety of real-world applications. These applications span from high-volume cloud services to mission-critical industrial systems.
One of the primary use cases is in manufacturing and logistics. In these sectors, computer vision is used for quality control, inventory management, and safety monitoring. The NVIDIA Jetson-based Flowbox is specifically targeted at these industries [1]. By pre-configuring these devices with the Inference framework, companies can deploy robust, secure vision systems on their factory floors. This allows for real-time analysis of production lines without the latency or security concerns associated with cloud processing.
Another key application is in the development of autonomous systems. Robots and autonomous vehicles require low-latency inference to make split-second decisions. The ability of Inference to run on tiny edge devices [1] makes it possible to deploy sophisticated AI models in constrained environments. The hardware acceleration provided by CUDA ensures that even these resource-constrained devices can perform complex computations efficiently.
Deployment Environments: Cloud vs. Edge
The choice between cloud and edge deployment often depends on specific operational constraints. The table below outlines the key differences based on the capabilities of the Inference framework and NVIDIA hardware.
| Feature | Cloud-Based Inference | Edge-Based Inference (Flowbox) |
|---|---|---|
| Hardware Context | Runs on beefy cloud servers with GPU acceleration [1, 3] | Runs on ruggedized NVIDIA Jetson modules [2, 3] |
| Network Dependency | Requires connection to cloud provider [1] | Optimized for secure, restricted networks [1] |
| Primary Use Case | High-volume training or centralized inference [1] | Secure, localized computer vision tasks [1] |
| Deployment Complexity | Managed via containers and orchestration [1] | Pre-configured, plug-and-play unit [1] |
In the cloud, the focus is on scalability and cost-efficiency. The inference server can spin up multiple containers to handle a high volume of requests, leveraging CUDA for performance [1]. In the edge, the focus is on reliability and security. The Flowbox provides a ruggedized solution that can withstand harsh environments, making it suitable for industrial settings [1].
Conclusion: The Future of AI Development
The convergence of NVIDIA’s hardware acceleration, secure edge computing, and open-source deployment frameworks like Inference is reshaping the AI landscape. This article has examined how CUDA provides the foundational software layer for high-performance GPU acceleration [1], how the Inference framework abstracts hardware differences to allow deployment from cloud servers to edge devices [3, 4], and how specialized hardware like the Flowbox addresses the specific security and durability needs of industrial applications [1].
Developers are no longer limited to choosing between raw power and portability. With CUDA providing the computational backbone and Inference providing the deployment flexibility, AI applications can be more powerful, secure, and accessible. As models become larger and more complex, the need for efficient hardware acceleration will only grow. Simultaneously, as AI moves into the physical world, the need for secure, localized inference will become critical.
By leveraging these technologies, developers can focus on innovation rather than infrastructure. The underlying complexity of GPU acceleration and edge deployment is abstracted away, allowing for the creation of sophisticated AI applications that can run anywhere, from the cloud to the factory floor. This integration of hardware and software tools represents the current standard for building robust, secure, and high-performance AI systems.
References
- roboflow/inference — github.com (7 November 2026)